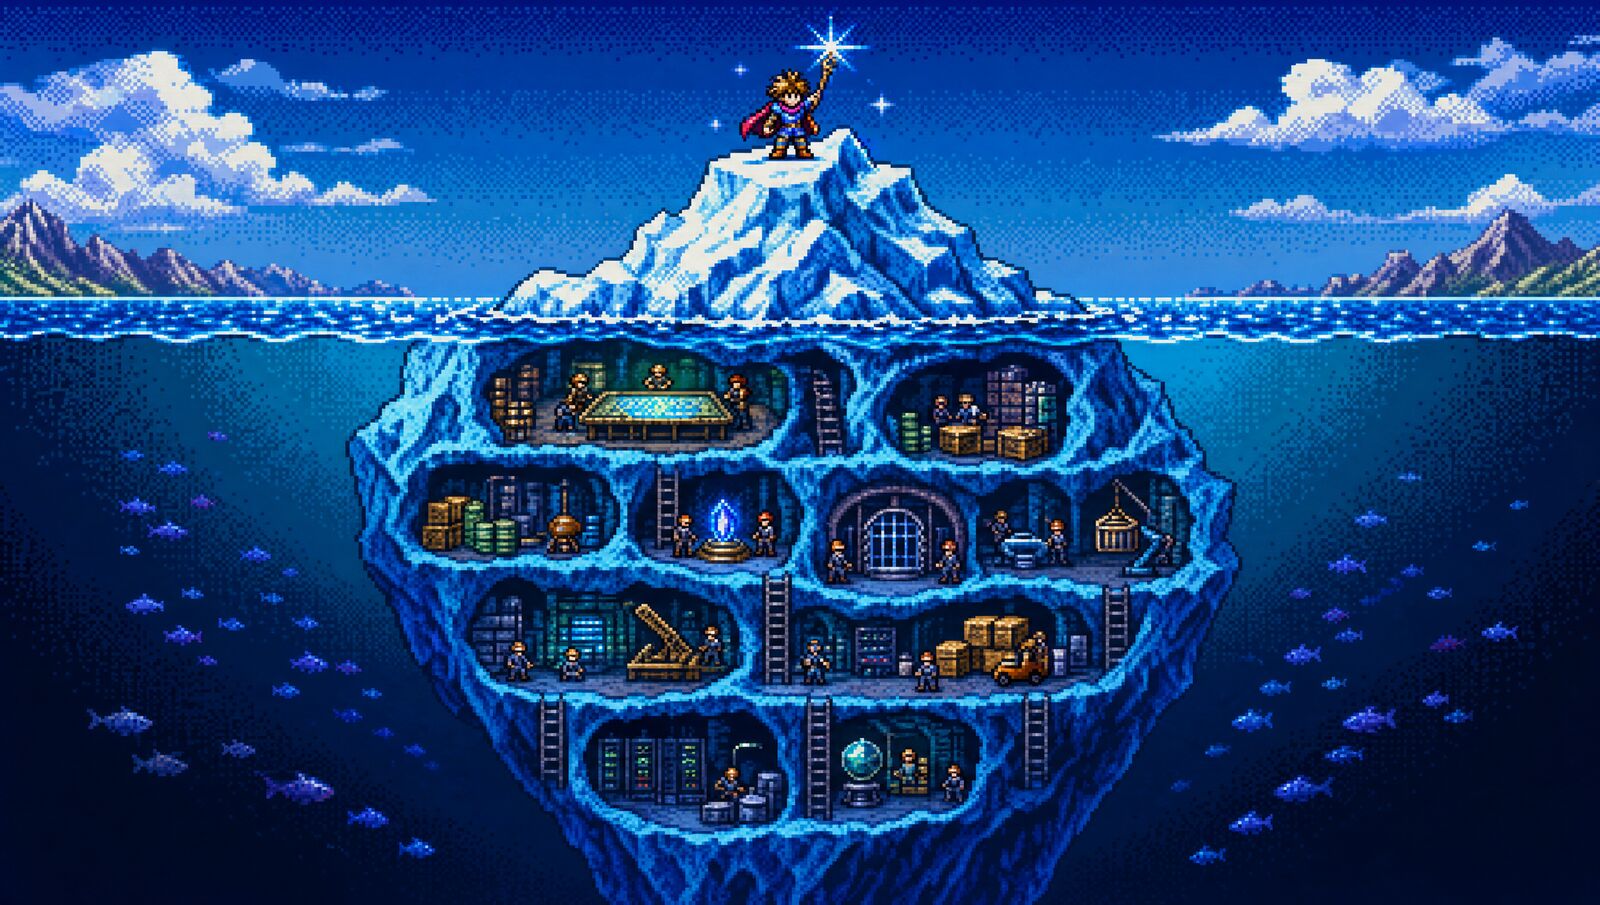
AI writes the first 20%. Shipping is the other 80%.
The first version of almost anything is now a few weeks’ work. Point a decent model at a problem, give it an orchestration library and a bit of retrieval, and you’ll have something that demos beautifully. People get excited. Budget gets approved.
Then somebody from risk or audit asks a plain question, and the room goes quiet.
Picture a head of audit at a bank, a few months into an agent pilot that everyone loved in week three. The external auditors arrive and ask to see every decision the system made, who authorised it, and what data it could see at that moment. The honest answer is that the evidence is in three places: a tracing tool, a logging table someone built by hand, and the model provider’s usage dashboard. They don’t agree. The table has gaps. The trace is missing the retrieved context. The dashboard knows what things cost and nothing about why they happened. That’s a composite, but I’d be surprised if anyone who has run an agent pilot in a regulated business doesn’t recognise it.
The model was fine. The code it wrote was probably fine too. What was missing was everything around it.
Writing the code was never the expensive part
I spent years building payments and trade-finance systems before any of this. The code was rarely what kept me up at night. What kept me up was the stuff you only notice when it’s missing. Knowing who changed what. Being able to show that a change was checked by someone other than its author. Having a sign-off a regulator would accept. Running the thing somewhere you actually trusted.
AI has made the code dramatically cheaper and left the rest roughly where it was. If anything the rest has got harder, because now there’s far more code arriving, from authors who aren’t people, at a pace no review process was designed for.
That’s the 80%. It doesn’t demo well. In my experience it’s where pilots go to die.
What the 80% actually is
When I strip it back, the things a regulated buyer needs before AI-built software goes anywhere near production come down to a short list.
Every agent needs its own identity. If agents act on a shared token or a human’s credentials, you can’t answer “which agent did this?” after something goes wrong, and with enough agents something will go wrong.
The work needs checking by something other than whatever produced it. A model marking its own homework is a demo. Independent verification is what lets you trust output you didn’t watch being written.
People need to approve the changes that matter, quickly, with the context in front of them. Only the ones that carry real risk. Approvals that are slow or arrive without context turn into rubber stamps, which I’d argue is worse than having none.
There has to be one record. Each change should leave a single account of who asked for it, which agent did it, what checked it, who approved it and under which rule. Spread that account across four tools with four clocks and it will disagree with itself on the day you need it most.
And the result needs a safe place to run. Isolated, patched, watched, and somewhere you chose. Software written in an afternoon still has to survive years in production.
None of this is new. Every decent engineering organisation has some version of it for human developers. The trouble is that the human versions lean on things agents don’t have: a named employee, a manager, a review culture, a change board that meets on Thursdays. Those don’t stretch to a few hundred agents opening changes around the clock.
Why bolting it on afterwards rarely works
The tempting move is to keep the working pilot and add governance around the edges. Monitoring here, a logging table there, an approval step in a chat tool.
I don’t think it holds, and the reason is mostly about the record. Monitoring tells you what happened after it happened. A record an auditor will accept has to be produced by the work itself, in one place, in order. If identity lives in one system, approvals in another, logs in a third and cost data in a fourth, you can’t later stitch them into a single consistent account. You’ll get something approximate, and to a regulator approximate tends to mean useless.
Cost is the same story. Gartner’s guidance on agentic AI project cancellations (press release, 25 June 2025) pointed to runaway cost and weak governance as leading causes. A Slack alert after the money has gone isn’t a spending limit. A real limit sits where the work is decided, before it runs. I’ve written more about that in cost governance before the invoice arrives.
What we’re building toward
This gap is why Deep Thinking exists. Kizuna is where AI agents build software under your rules: each agent has an identity, its work is independently verified, people approve what matters, and every change leaves one record. Voxeltron is where that software then runs, deployed, isolated, secured and kept running on infrastructure you choose. We’re still building both and our pilot programme is open, so I’ll leave it at what they’re for.
The framing matters more to me than our products, though. If you’re evaluating anything in this space, ours included, ask about the 80% first.
Questions worth asking before a pilot starts
A few that tend to separate a demo from something that can go to production:
- Can you show which agent made a specific change, and prove it wasn’t a person or another agent using the same credentials?
- What checked this change, and was it independent of whatever wrote it?
- Where is the human approval recorded, and is it in the same record as the agent’s work?
- Six months from now, can you reconstruct what happened from one account, without stitching exports together?
- Where does the software run, who can reach it, and how quickly can it be patched?
- What stops spend before it happens, as opposed to telling you afterwards?
If you get confident answers and a live demonstration, good. If you get a slide, keep asking.
Testing the 80% in your own environment
You don’t need a big commitment to find out whether any of this holds. Pick one well-understood workflow with a known cost and a clear before state. A quarterly control test, say, or a piece of internal tooling a team keeps putting off.
Run it under a hard budget for the first month and check the system stops itself when it should. In the second month, hand the output and its record to someone who thinks like an auditor and ask them to find a gap. In the third, run it for real and measure how long changes take from request to release, how often a person had to step in and how long that took, and whether spend ever crossed the line. If it did, you’ve learned something cheaply.
What you’re really testing is whether the system around the code holds up. AI hasn’t made that part cheap yet. My bet is that it’s the part that decides who gets AI-built software into production at all.
If you’re working through this in your own organisation, we’d like to hear from you.